Ternary Bonsai 2: a 27B model in 6GB — AI Digest
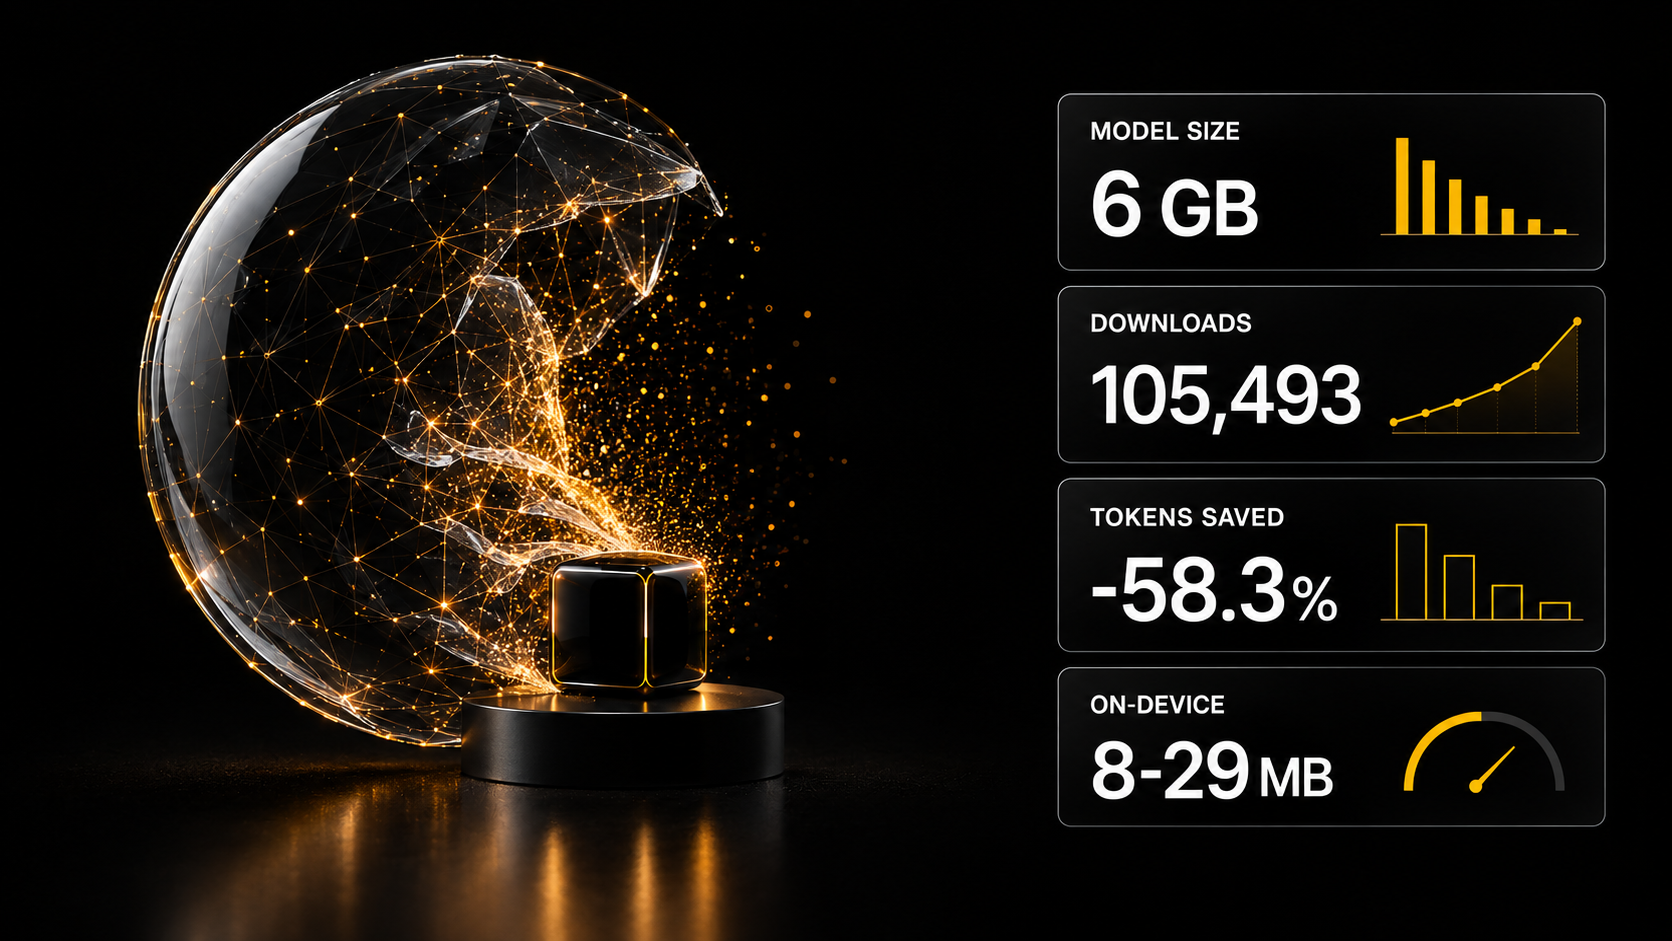
Ternary Bonsai 2 squeezed Qwen3.8-27B into 6GB and runs in a browser at a claimed 98.2% of quality. Swift Qwen 3.8 27B took 105,493 downloads in six days on −58.3% tokens, and Cactus Needle 3 parses commands on a CPU in 8–29MB.
Today's highlights
Ternary Bonsai 2: a 27B model that fits in 6GB and runs in a browser
Ternary Bonsai 2, a ternary derivative of Qwen3.8-27B, takes under 6GB — nine times smaller than the FP16 version — at a claimed 98.2% of retained quality. A ternary model is one whose every weight is restricted to three values instead of a fractional number, and that alone produces the size collapse without touching the architecture: the original 27-billion-parameter hybrid causal LM is preserved intact. The collection sits on Hugging Face together with an in-browser WebGPU demo, which means a model of this class now starts on an ordinary laptop with nothing installed. On 18 September 2026 the 98.2% figure met a cool reception: nobody has run an independent check, and one tester reported the browser demo looping on Rust questions.
Swift Qwen 3.8 27B: 105,493 downloads in six days on a promise to think less
Swift Qwen 3.8 27B collected 105,493 downloads in six days, reaching first place among Hugging Face fine-tunes and ninth in the overall trending list. Its authors target cost rather than answer quality: the fine-tune attacks redundant reasoning and claims −58.3% tokens spent and a 1.95x speedup with no loss of accuracy. Growth was steep — from 24,000 downloads on day two to 105,493 on day six. The community reaction is the telling part: users rebuilt the model for their own runtimes almost immediately, one porting it to NInfer V3 and reporting a full 262,000-token context with vision on an RTX 5090, another converting the NVFP4 quantization into GGUF for llama.cpp compatibility.
Cactus Needle 3: 8–29MB of CPU automation against 88.4 for DeepSeek V4 Flash
Cactus Needle 3, a family of function-calling models shipping as 8–29MB CPU-only binaries, scores 86.0 on Mobile Actions against 88.4 for DeepSeek V4 Flash. Function calling is the mode where a model returns a structured tool invocation with parameters instead of prose; here it is held in place by a grammar that cannot leave valid JSON. The family slices by depth — 2 to 20 layers, 25 to 121 million deployable parameters — an "intelligence ladder" where you take the smallest layer count that still solves the task. Four tenths of a percent behind a frontier model at three orders of magnitude less size is the core argument for moving command parsing off the server and onto the device. Ready scaffolding for that pattern lives in the AI SKILLS automation templates.
Mollick: today's models already do weeks of work, and almost nobody uses that
Ethan Mollick argues in his 18 September 2026 essay "The Overhang" that GPT-6 Astra and Fable 5.1 are already sufficient for transformative impact across large parts of the economy, and are barely being used. He backs it with his own runs: Astra turned the 1977 text game Zork into a full 3D action-adventure, deciding on its own what the white house and the grue look like, since the original only mentions them. Fable 5.1 reconstructed Umberto Eco's library from a dozen videos, the foundation's photographs and two catalogues: it read spines frame by frame, inferred the floor plan and placed roughly 5,000 identified books across 27,000 shelf slots, marking each one certain, guess or unknown. Mollick's own book trailer took 45 minutes — the model taught itself Blender, wrote the script, built the 3D scene and scored it.
Numbers and facts
- Laya — a 421M-parameter reproduction of a closed decision model: a claimed 38.4ms latency against roughly 400ms for the original, built on a ModernBERT-large encoder with a scoring head; weights on Hugging Face.
- Factorio: Space Age — Vals AI claims GPT-6 Astra completed the game: over 165 in-game hours in roughly two days of wall-clock time. Commenters on 18 September 2026 are asking for a recording: without one it is unclear whether the game ran accelerated (discussion).
- Cactus Needle 3, deployable size — 25 to 121 million parameters at CQ2 quantization in 8–29MB binaries; the model is English-first, and other languages tokenize less efficiently (announcement).
- Our own data: on 20 September 2026 four new projects totalling 7,500 stars were added to the Open Source section on AI SKILLS — an AI subtitle generator, a rootless Alpine Linux runtime for Android, an exposed-host scanner and an intercepting proxy. These figures come from our database and appear in no primary source.
Different views: how much quality survives compression
The argument on 18 September 2026 turns on a single number — the 98.2% of retained quality claimed for Ternary Bonsai 2 at a ninefold size reduction. There is nothing to check it against yet: nobody has published an independent measurement.
For. The practical appeal is plain: a 27-billion-parameter model that fits in 6GB and starts in a browser is reachable on hardware where frontier models are simply out of the question, and a model you can run beats one you cannot.
Neutral. The community says outright that it intends to test the claim itself: the authors' retention figure is being treated as a hypothesis rather than a result, and until independent runs exist the 98.2% cannot be cited as fact.
Against. One observation already exists: the browser demo looped on Rust questions. That may be a WebGPU execution defect or a compression artefact, and without measurements the two explanations cannot be separated — which is exactly why the number remains a claim.
Tools and techniques
- Convert for your runtime instead of changing your runtime. Within days the community rebuilt Swift Qwen 3.8 27B for llama.cpp via GGUF and for NInfer V3 with an NVFP4 KV cache — a full 262,000-token context with vision on a single RTX 5090. Before buying hardware for a model, check whether someone has already rebuilt it for what you own.
- Take the smallest depth that solves the task. The Cactus Needle 3 "intelligence ladder" — 2 to 20 layers — lets you match a layer count to a specific parsing job rather than defaulting to the maximum; local LoRA fine-tuning and export ship with it (description).
- Try what you already pay for first. Mollick's thesis is cheap to test: take a task that costs your team a week and hand it to your current model whole, without splitting it into steps (essay). The AI SKILLS prompt generator helps with the wording.
In brief
- California Governor Gavin Newsom signed an executive order convening an expert panel on AI safety legislation, with kill switches, embedded outside monitors and mandatory safety plans among the measures under discussion (reported by The Rundown).
- Figure showed Helix 2.5, the next generation of its humanoid platform, which Superhuman covered in a dedicated 19 September 2026 issue.
- Claude Code is getting Mods, a mechanism that changes how the tool itself looks and behaves, while Artifacts gains dedicated products for documents and slides (Ben's Bites breakdown).
- Ternary Bonsai 2 keeps the Qwen3.8-27B architecture untouched — the ninefold reduction comes from weights alone, not from cutting layers (collection card).