12 Claude Code Skills Worth Installing (Out of 10,441)
Publishing a skill costs nothing, so most of what exists is a saved prompt with front matter bolted on. Four rules, twelve skills, and what changes when a team commits the folder.
A Claude Code skill is a folder with a SKILL.md file in it. You put it in .claude/skills/ inside your project, and Claude reads it when the task matches — you do not have to mention it. That simplicity is why there are now thousands of them published, and why most of them are not worth the disk space.
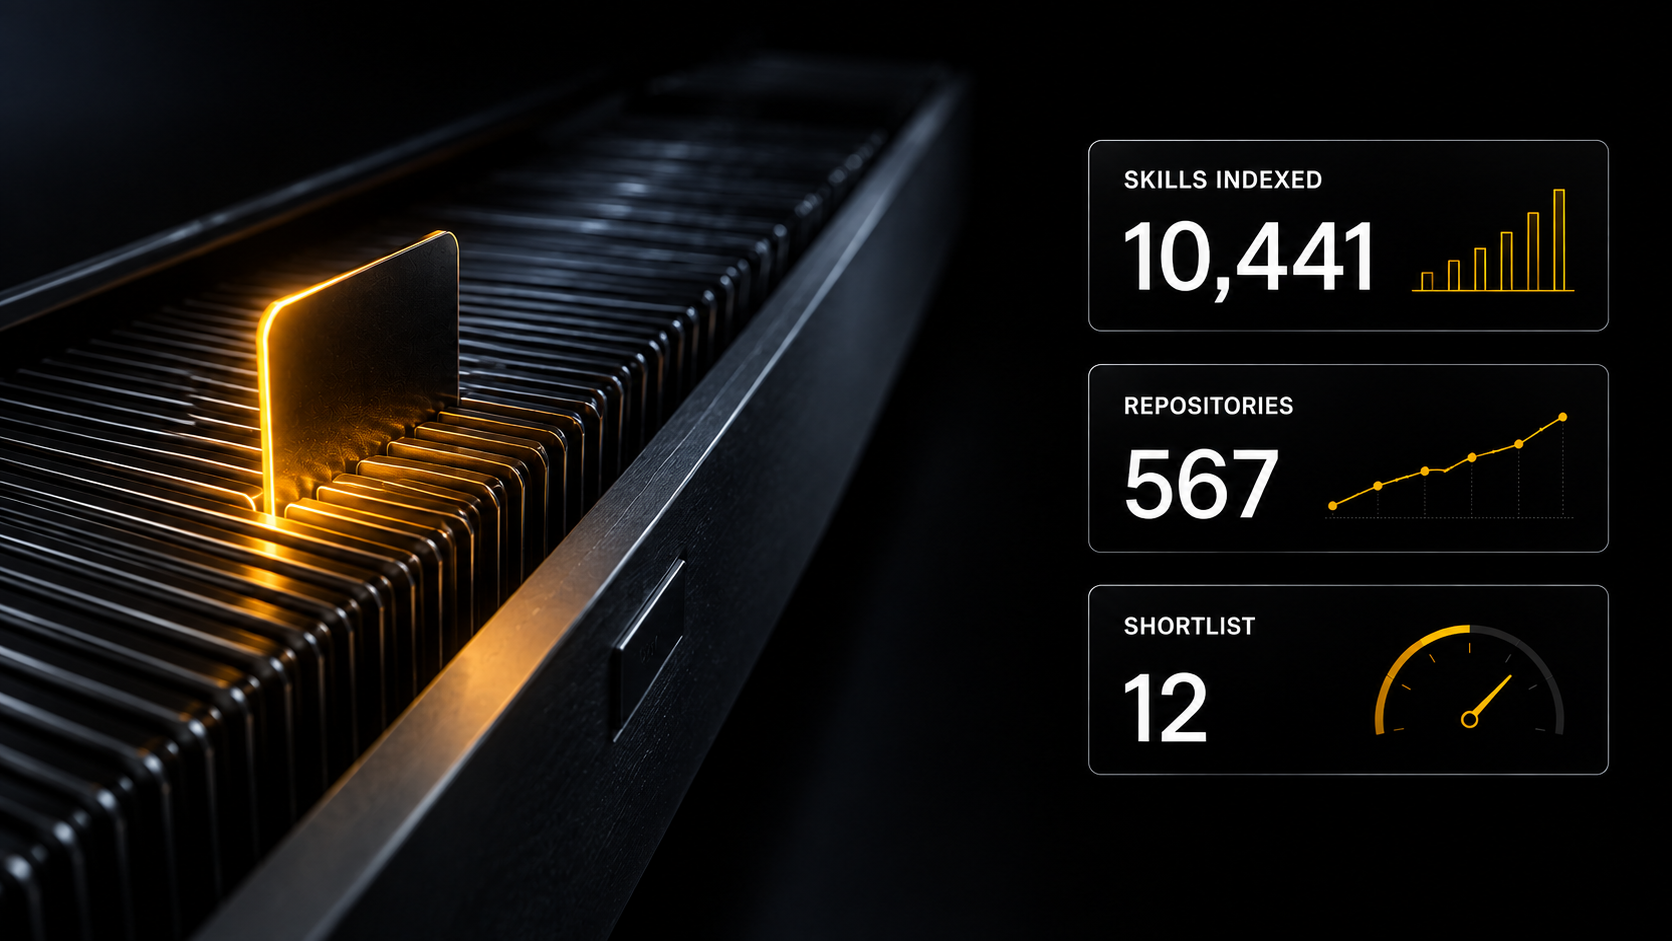
We index every public repository that ships skills — 10,441 of them right now, each read and described by hand in the Claude Code skills catalogue. This is what we learned sorting through them, and the twelve we would install in a working repository today.
What a skill actually is
SKILL.md has YAML front matter — a name and a description of when the skill applies — followed by ordinary instructions in Markdown. Claude keeps the descriptions of every installed skill in view and loads the full text of one only when it is needed. A skill folder can carry more than prose: scripts/ for the parts that should be deterministic, references/ for material pulled in on demand, assets/ for templates the output is built from.
The difference from a prompt is where it lives and when it fires. A prompt sits in your notes and you paste it again every time. A skill sits in the repository next to the code, goes through review like any other file, and works for everyone who clones the project.
Why a shortlist is needed
Publishing a skill costs nothing, so a large share of what exists is a prompt someone saved with front matter bolted on top. Those skills restate the documentation of a tool, stop at the interesting part, or describe a workflow the author never ran twice. They are not harmful — they are noise, and noise has a price: every installed skill spends description budget in the model's context whether it fires or not.
The shape of the catalogue today: 10,441 active skills across 567 repositories. The largest single collection supplies about three thousand of them on its own. By job, the biggest shelf is integrations — 2,511 skills, roughly one per external service — followed by 1,388 for coding itself, 917 general-purpose, 826 marketing, 587 engineering practice, 573 content, 357 testing and 327 documentation. Writing code is a minority of what people publish skills for, which is worth knowing before you go looking.
Four rules got us from ten thousand to twelve.
It owns a whole job. "Review this pull request and post the result" is a job. "Write a good commit message" is a step inside one, and Claude does not need a file for it.
It ships more than prose. Scripts, reference files, templates, worked examples. A skill that is only instructions is a prompt with extra steps.
It says what it will not do. The best files in the catalogue name their boundary in the first paragraph. A skill that claims everything decides nothing.
It lives in a codebase that uses it. Stars on the host repository measure the project, not the skill — but a skill maintained inside something that ships daily has been corrected by reality, and one in an empty repository has not. We used it as a tiebreaker, not as the test, which is why five of the twelve below come from repositories with fewer than 200 stars.
Pull requests and code review
pr-reviewer collects everything about a pull request first — metadata, diff, comments, commits, linked issues — and writes three separate files: a detailed internal review, a clean version for publication, and a list of proposed inline comments. Nothing reaches GitHub until you type /send. The two-step publication is the reason it is on this list; most review skills post first.
handle-pr-comments, maintained inside Storybook, walks unresolved review threads one at a time through the GraphQL reviewThreads API. For each thread it reads the surrounding code, summarises the feedback, proposes a fix, and asks whether to apply it, answer only, or skip. Human reviewers are handled before bots. It is the only skill we found that treats a review thread as a conversation rather than a list.
my-pr-checker takes the other side: your own pull request after review. It checks CI, works through inline and top-level comments — including the dozens that Copilot and CodeRabbit leave — commits fixes, pushes, and iterates until the checks are green and the threads are resolved.
contrib-pr-review reviews a pull request from outside the project, and it is the only one in this list that treats a contribution as a possible attack: it looks for changes to .github/ workflows combined with pull_request_target, and for edits to AGENTS.md and the agent configuration itself. If you accept outside contributions to a repository an agent reads, install this one first.
More in the GitHub skills hub.
Documentation
documentation, from Anthropic's own knowledge-work plugins, covers READMEs, API reference, runbooks, architecture notes and onboarding guides, with a different structure for each: a README aims at a first working result in five minutes, API docs cover authentication, error codes and SDK examples, a runbook carries rollback steps and escalation paths.
update-docs, maintained inside Anytype, keeps a README next to the code it describes and edits only the sections a change actually touched. Delta-oriented rather than regenerate-everything — which is the difference between documentation that stays current and documentation nobody trusts.
author-product-docs organises user documentation by Diátaxis — tutorials, how-to guides, reference, explanation — and refuses to state anything about product behaviour before reading the source files. It also names what it is not for: feature specs, RFCs and ADRs are explicitly out of scope.
crafting-effective-readmes starts by asking what you are doing — writing from scratch, adding a section, updating stale content, or reviewing — then picks one of four templates by audience: open source, personal project, internal tool, config repository. A README for contributors is not a README for your future self, and it is the rare skill that says so.
More in the documentation hub.
Repository standards and skills of your own
managing-git-workflow, from the HASH monorepo, fixes branch names, pull request titles and the template body, then carries the change through a merge queue and back to the tracker issue. This is the skill to read if you want to see what "the whole team works the same way" looks like written down.
documentation-guide ships a requirement matrix: which documents are mandatory, recommended or unnecessary depending on whether the work is a new project, a refactor, a migration or maintenance — across README, ARCHITECTURE, API, DATABASE, DEPLOYMENT, MIGRATION, ADR and CHANGELOG.
skill-creator is the one to install before you write your own. It documents the full anatomy of a skill package — required front matter, scripts/, references/, assets/ — and the progressive-disclosure pattern that keeps SKILL.md short by moving detail into bundled files.
atopile-skills is the maintenance counterpart, and it is the most underrated file in this list. It describes how to keep your own SKILL.md files true: find the primary source, verify every claim against the code with rg, fix stale paths and APIs, keep a Quick Start of five to twenty lines. Skills rot exactly like documentation rots, and almost nobody writes down how to stop it.
More in the team skills hub.
Installing one
Put the file at .claude/skills/<name>/SKILL.md inside your project and describe your task to Claude in ordinary words. There is nothing to configure and nothing to restart. A skill placed in your user directory instead follows you across every project; a skill committed to the repository follows the project across every person.
Start with two or three. Every installed skill keeps its description in context, so a folder of forty is worse than a folder of four — Claude spends attention deciding between them, and picks wrong more often.
What changes when a team shares them
Commit the folder. That single decision is most of the value, and it is what people mean when they ask about sharing skills with a team: the review rules, the commit format, the release checklist and the framework conventions stop being something each person remembers differently.
Two habits make it hold. Review skill changes like code — a skill is an instruction to an agent with write access to your repository, and it deserves the same scrutiny as a script. And delete skills that stopped being used; a stale skill is worse than a missing one, because it will still fire.
Where the rest are
The catalogue is open without registration — every card, description and category is readable by anyone. The SKILL.md file itself and the link to the original repository come with a subscription, from the Basic tier up.
By job: GitHub · documentation · testing · security · teams · content · SEO · design.
FAQ
Where do Claude Code skills come from on GitHub?
Most of them live inside ordinary project repositories, in a .claude/skills/ folder next to the code — not in dedicated skill repositories. That is why they are hard to find by searching GitHub directly: the skill is a subfolder of a project whose name has nothing to do with it. Our catalogue indexes those folders and describes each one separately.
How many skills should one project have?
Fewer than feels right. Every installed skill keeps its description in the model's context, so a large folder makes the choice harder, not richer. Three to eight that each own a real job beat forty that overlap.
How do you share skills across a team?
Commit .claude/skills/ to the repository. Everyone who clones the project gets them, changes go through review like any other file, and the history shows who changed a rule and when. Skills kept in a personal directory follow the person instead of the project, which is the opposite of what a team wants.
Can a skill do damage?
A skill is an instruction to an agent that can write files and run commands, so yes — treat one you did not write like any other dependency. Read SKILL.md and anything in scripts/ before installing, and be especially careful with skills that touch CI configuration. This is also why contrib-pr-review above checks incoming pull requests for edits to agent configuration.
Do skills work outside Claude Code?
The format is Claude's, but several catalogue entries ship the same instructions for other agent tools as well. If portability matters, prefer skills whose logic is in scripts/ — those move; prose tuned to one model does not.