Opus 5.5 Ships 90 ASP.NET Core PRs for $230 — AI Digest
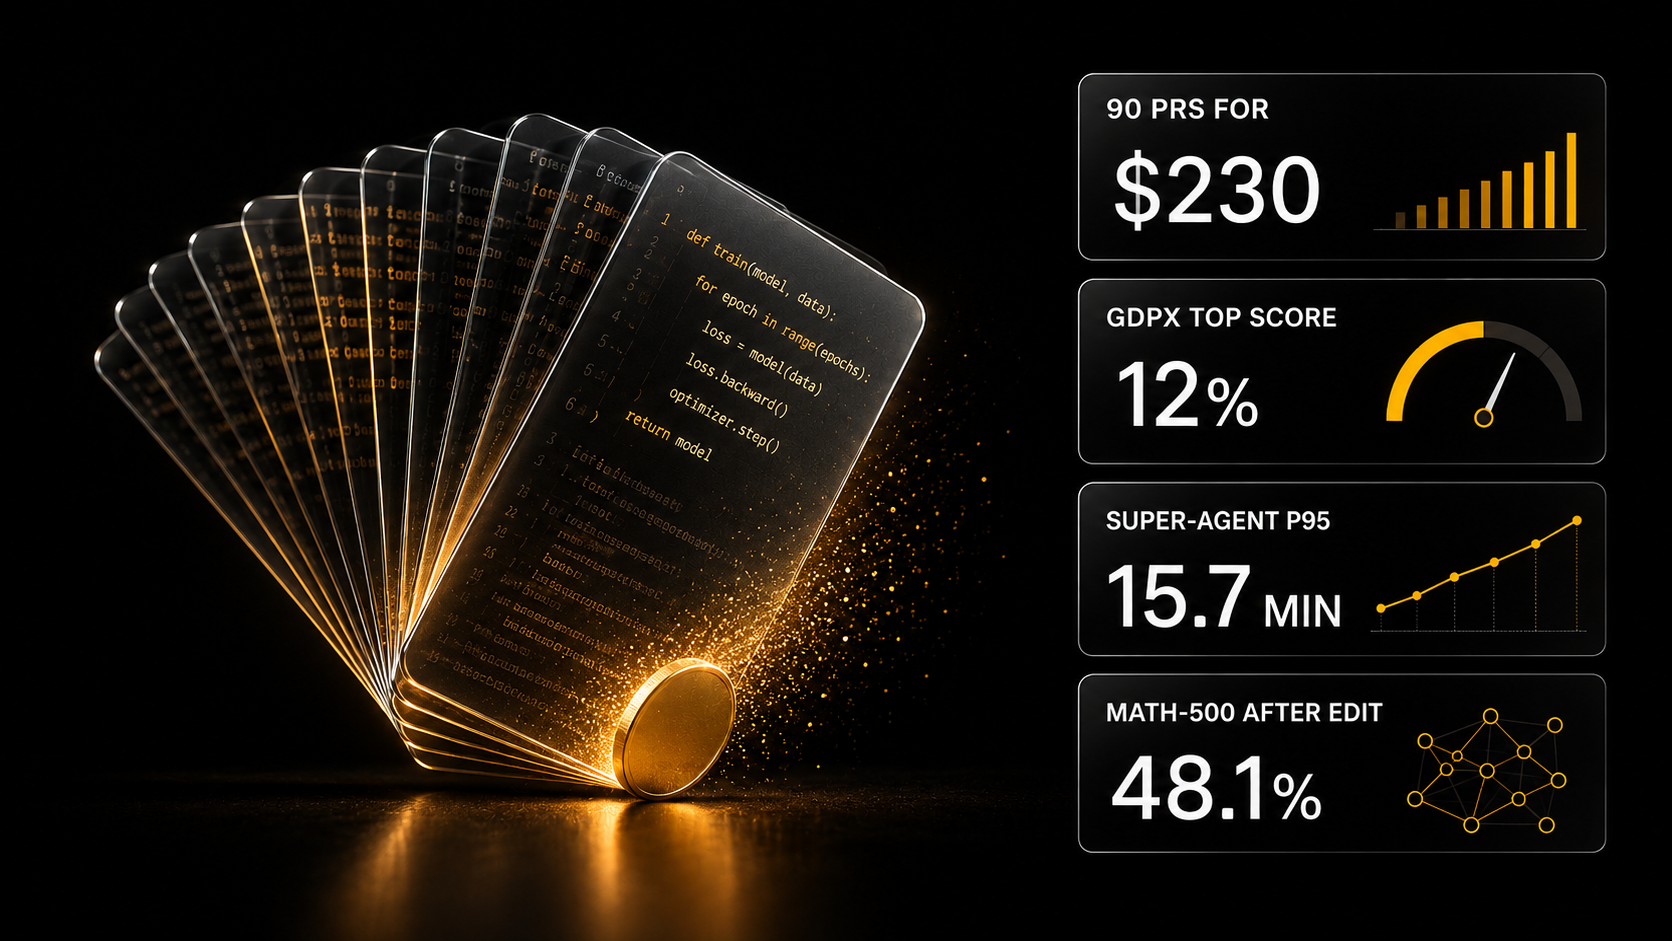
An Opus 5.5 agent shipped about 90 ASP.NET Core performance PRs for $230, roughly $2.60 each. On the GDPx benchmark the best model solves only 12% of economic tasks, and DeepSeek open-sourced its super-agent harness.
What matters for you today: an agent running on Opus 5.5 shipped about 90 code changes for $230, roughly $2.60 per change, so the cost of routine technical work dropped again. Yet on the hardest economically valuable tasks the best model still succeeds only 12% of the time. Sell the outcome and the review, not the hours.
Top stories
Opus 5.5 and GitHub cloud agents: about 90 ASP.NET Core PRs for $230
David Fowler got about 90 performance pull requests for ASP.NET Core in a single day by running GitHub's new cloud agents on Claude Opus 5.5; the tokens cost about $230.
I did the math: $230 across 90 changes is about $2.60 each. ASP.NET Core is Microsoft's open-source web framework, so this is a large, reviewed codebase rather than a toy project. A pull request is a proposed code change that a human reviews and then merges or rejects.
What it means: client work. When an agent produces a change for a few dollars, the value moves to framing the task and checking the result: someone still has to read 90 changes before they are merged. Price the review, not the typing.
Sources: David Fowler
Karpathy: a service built from 43M Hacker News comments in 2 hours
Andrej Karpathy built HackerTube, a catalog of 6,454 videos that Hacker News commenters recommended again and again over 20 years; Claude filtered 43 million comments, and the whole build took about 2 hours.
He worked in Claude Code desktop on Opus 5.5 at Medium effort, and those 2 hours included hardening the VPS and deploying it. The Medium default reopened the debate about when the pricier effort levels are worth it (Yuchen Jin, swyx). DAIR immediately built the same kind of list for research papers, covering more than 1,000 of them.
What it means: client work. "Turn a huge archive into a useful showcase" is a service any client understands. The build now takes hours; what you sell is the judgment about which data to keep and who it is for.
Sources: Andrej Karpathy · DAIR, Hacker Papers
Local models vs Claude on 9 real bugs: 0.50 vs 0.74
In an independent test on 9 private C++/CUDA bug-fix tasks, the best local model, Qwen3.8-Flash-Next in NVFP4, scored 0.50, against 0.74 for Claude Opus 5.5 and 0.58 for Claude Sonnet 5.5.
That puts the local model at roughly two thirds of Opus 5.5. Quantization is compressing a model's weights to fewer bits so that it fits on a home GPU. In this small test, compression barely hurt accuracy, but the 3-bit build of Qwen3.8-27B needed 1.4 times more tokens per task. Tokens per second is therefore misleading; bugs fixed per minute is the number to watch.
What it means: business. If code or documents cannot leave your premises, a local model already handles a meaningful share of tasks, just not on par with Opus. Our guide to open-weight LLMs covers picking a model for private data.
Sources: r/LocalLLaMA, 9-bug test
SemiAnalysis GDPx: the best model solves 12% of economic tasks
SemiAnalysis launched GDPx, a benchmark of 206 agentic tasks across 11 economically valuable domains, including chip design, software engineering, finance and biology; the top score is 12%, from Claude Opus 5.5.
Gemini 4 Carbon scored 10.9% and, per kimmonismus's breakdown, costs roughly 4 times less. Analyst Elie Bakouch showed that removing tasks where models hit safety safeguards changes the picture, and Sol 6.1 comes out cheaper still. The benchmark is closed, and critics point out that auditing it is expensive.
What it means: profession and trust. For a financial analyst, an engineer or a biologist, this answers "will an agent replace me": on long professional tasks, not yet, since the best model fails 88% of them. Agents speed up pieces of the work; the specialist still owns the result.
Sources: SemiAnalysis · kimmonismus · Elie Bakouch
DeepSeek open-sources a super-agent prototype: p95 from 29.5 to 15.7 minutes
DeepSeek published a design article and the dsh-superagent-prototype repository, a harness where one long-lived router session talks to the human and hands work to isolated workers; in DeepSeek's own test, 95th-percentile completion time fell from 29.5 to 15.7 minutes.
A harness is the scaffolding around a model: tools, memory, rules and workflow. Think of it as the kitchen around the chef. Workers run in parallel and are triggered by GitHub events. The baseline was a single session spawning its own subagents. Reviewer Cui Tianyi writes that "Super" means a layer above the agent, not superior intelligence, and lists the gaps: no long-term memory across sessions, untested security, and validation only in a trusted internal environment.
What it means: for builders, a ready pattern of one dispatcher plus many workers. We walked through building it on n8n for a team chat in our DeepSeek super-agent master class.
Sources: DeepSeek Harness · kimmonismus · Zhihu Frontier
DeepSeek-V4.1-Flash-1017 at 1 bit: 72 GB instead of 138 GB
ISTA DAS Lab released a coding build of the 763-billion-parameter DeepSeek-V4.1-Flash-1017 at 1.05 bits per parameter: the transformer weights take 72.1 GB, versus 138.2 GB for the previous compressed build.
Half of the experts in every layer were pruned and the rest quantized. The model kept 98.7% of its LiveCodeBench v6 score (88.57 vs 89.71) and 94.8% on SWE-bench Verified (77.00 vs 81.20). Shared Engram weights add another 110.6 GB. Separately, a hobbyist patched the Strata engine so that a new DeepSeek V4.1 Flash agent session on an RX 9070 XT gaming GPU with 16 GB and 64 GB of RAM starts in 5 seconds instead of 100.
What it means: your wallet. Near-frontier models are moving onto home hardware, though commenters fairly ask why bother with 763B parameters when, by their numbers, Qwen3.8-27B scores 90.3 on LiveCodeBench.
Sources: r/LocalLLaMA, ISTA · Hugging Face · r/LocalLLaMA, Strata
Weight-Space Programming: editing 0.016% of weights lifts MATH-500 from 7.9% to 48.1%
MIT CSAIL researchers showed that frontier models can read and edit the weights of small neural networks from a natural-language goal, without gradient-descent training; editing 131,072 weights (about 0.016%) of Qwen3.5-0.8B raised its MATH-500 score from 7.9% to 48.1%.
In other experiments the model identified the behavior of small networks from raw weights, wrote game-playing networks from scratch, and repaired a broken control policy by changing 3.5% of its weights. Skeptics on r/LocalLLaMA note that the low baseline came from the model looping until it hit the token limit (93% of runs before the edit, 33% after), and that the trick failed on Gemma 3 270M, which lacks that problem.
What it means: for builders, a new tool for inspecting models rather than a way to "train without data." I would wait for independent replications on harder tasks.
Sources: Takehi et al. · r/LocalLLaMA, discussion · r/LocalLLaMA, MATH-500 critique
Numbers and facts
| Number | What it is | What it means in practice |
|---|---|---|
| 159 | Epoch Capabilities Index for DeepSeek V4.1F-1017, equal to GPT 5.5 and 10 points above V4-Pro (teortaxesTex) | an open model now sits at the level of OpenAI's previous flagship |
| 36 hours and about $2,000 | what Devin spent porting a model to run cheaply on Trainium (Nader Dabit) | infrastructure ports are becoming a weekend job for an agent |
| 30x | cheaper: the same work on GLM 5.3-Flash vs Grok 4.7; skipping compaction at about 200k tokens improved efficiency by up to 23% (evalstate) | price per task matters more than price per token |
| $5.75 per hour | renting one B300 GPU in a 128-GPU cluster (teortaxesTex) | owning hardware takes about a year to break even, even at DeepSeek-level revenue |
| Over $5B a year | the annualized OpenRouter spend driven by Opus (Deedy Das) | demand for the expensive agent model is not slowing |
| 15 releases, 500B tokens | what Vals ran through its evals in October 2026 (nikilravi) | a model worth testing ships every other day |
| 10,696 | active Claude Code skills in the AI SKILLS catalog as of November 3, 2026 | ready-made skills for the agents in this issue are in the skills catalog |
Different views: does an agent need one long-lived "dispatcher"?
DeepSeek's pattern, one dispatcher session plus parallel workers, nearly halved 95th-percentile task time in the company's own test (29.5 to 15.7 minutes). The debate is whether this is a general recipe or a crutch for one specific model.
- For. The author of the pi agent says the design matches where Earendil is heading: a single long-lived entity, recursive delegation and triggers from external events (badlogicgames). A DAIR researcher calls the article a master class in harness design (omarsar0).
- Neutral. Reviewer Cui Tianyi acknowledges that other teams explored similar architectures earlier, and says DeepSeek aims to support pi and other major harnesses with each model generation (tianyi).
- Against. teortaxesTex calls the article "something of a hot mess" and argues DeepSeek builds internal crutches around model weaknesses such as hallucination instead of making the system generally robust (teortaxesTex).
Tools and tips
- Document extraction cheaper than the flagships. LlamaIndex shipped Extract Max Effort and claims it pulls data from documents more accurately than Astra or Opus at maximum settings, at a lower cost (Jerry Liu). What you get: invoices, contracts and forms turned into a table without manual copying.
- Agent permissions limited to the approved plan. Vercel issues agents tokens carrying only the scopes declared in the approved plan (Deep Learning Weekly). What you get: an agent with access to work systems cannot do more than what was agreed.
- Game-ready 3D objects from a 4B model. GLB-3D-Coder writes Three.js scenes that export GLB for Godot and other engines, across 25 asset categories (r/LocalLLaMA, Hugging Face). What you get: placeholder characters, weapons and buildings for a game prototype on your own machine.
In brief
- Qwen 4.0 and Qwen 5.0 will stay open: Qwen's head confirmed open weights; the team has released more than 460 open models with over 3 billion downloads (r/LocalLLaMA).
- Mythos 5.5: the name appeared in the HTML of Anthropic's site, described as "our most capable model class for cybersecurity and biology research"; there is no official announcement (kimmonismus).
- GPT-6.2 Astra: per unconfirmed reports, the model already shows up in Codex usage analytics, with a release expected soon (kimmonismus).
- Memdoor: a team of 5 Qwen3.8-27B models (a planner, two ideators, a solver and a manager) beat Fable 5 on LiveCodeBench Hard (r/LocalLLaMA).
- MiniMax M3.1 Flash, 428B parameters: Unsloth shipped 2-bit GGUF builds at 143.9 GB (MiniMax).
- FineDNA: Hugging Face released more than 300B tokens of genomic data and Carbon-X, the strongest open model on DNA tasks (Lewis Tunstall).
- LeCun and Balestriero's JEPA: image-text alignment with 42 times fewer examples, 21.6M versus 900M (heyshrutimishra).
- Sakana Sawara: Sakana AI announced an in-house language model, with Sawara Small planned for spring 2027 (hardmaru).
- Texas and datacenters: SemiAnalysis says 2027 capacity is largely locked in, and a Texas permit freeze is the biggest single risk to the 2028 US buildout (SemiAnalysis).
- US productivity: John Burn-Murdoch shows the uptick predates AI and appears only in the US, so it does not look like an AI effect (John Burn-Murdoch).