AI API pricing in 2026: how token economics work and what a request costs
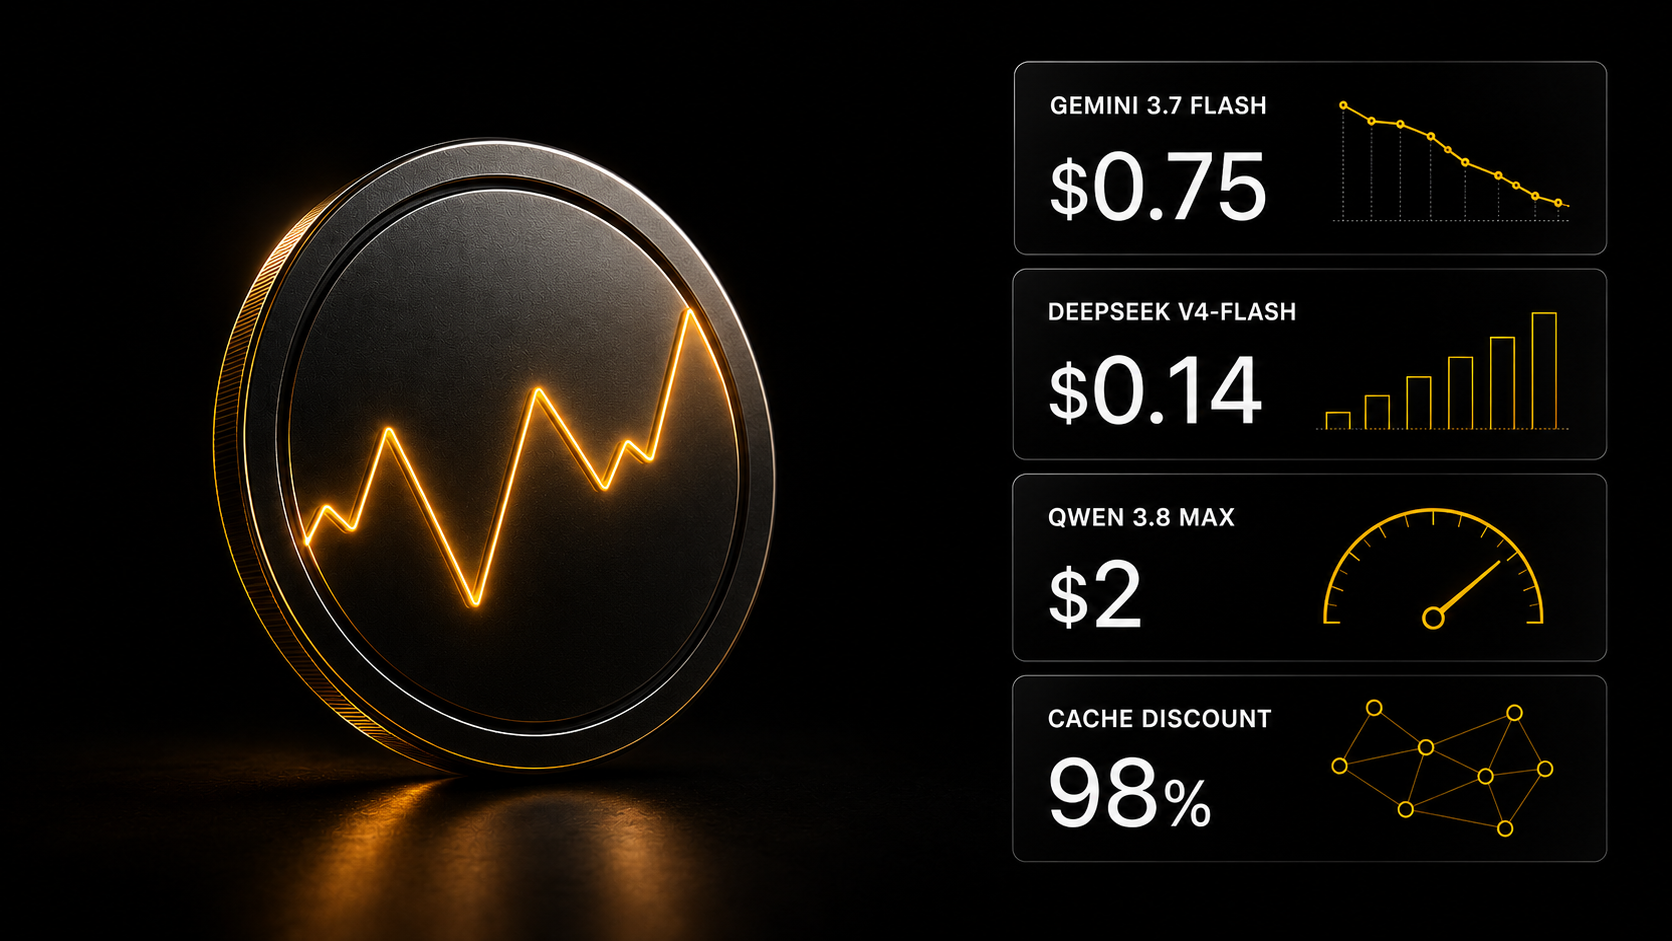
When you call a model through an API, the bill has three parts: for what you sent, for what it answered, and — usually cheaper — for what had already been processed before.
When you call a model through an API, the bill has three parts: for what you sent, for what it answered, and — usually cheaper — for what had already been processed before.
The counting is in tokens rather than characters: fragments of words. So the total depends on the length of your request, the volume of the answer, and how well the repeating text gets reused.
Below: what a token is and what makes up the bill, why the answer costs more than the request, what the discount on repeats is for, why prices swing, which costs are invisible in the price list, how to build this into a client's quote and how to keep the budget under control.
All prices carry a link to the original source as of 3 September 2026. Tariffs change, so always verify the current figure with the provider.
The guide is live: provider prices move and the tables follow them.
The short version
A token is a fragment of a word. You pay both for what is sent and for what comes back.
The answer costs more than the request — often by 2–5 times. Asking for shorter answers is a direct saving.
Repeating text costs several times less. With some models the discount reaches 98%.
The right question is not "what does the subscription cost" but "what did this job cost me".
The price list does not show everything. Hidden reasoning, retries and failed generations are not in the pricing table.
For a freelancer the key point: the cost of generations goes into the client's quote the same way paper goes into a printer's.
Part 1. What a token is and what makes up the bill
A token is the unit of text a model operates on: roughly part of a word. On average one token is 3–4 characters.
The bill has three parts:
Input — everything you sent: the question itself, the system instruction, the conversation history, attached documents.
Output — what the model wrote back.
Cached — the part of the input the provider has already processed before and keeps.
Prices are quoted separately for each part because they cost different amounts.
Why the answer costs more than the request
Output tokens are almost always more expensive than input, often by 2–5 times.
The reason is technical: the model can read your request whole and at once, whereas each word of the answer is computed sequentially, one after another.
The practical conclusion: a long answer costs more than a long request. Where you can, ask for shorter, more structured answers — that is a direct saving.
And separately: with models that "reason" before answering, hidden reasoning tokens are added to the output. You do not see them, but you pay for them at the output rate.
What the discount on repeats is for
If you send the same system instruction or the same long document in every request, the provider does not need to process that chunk again. So it costs several times less.
In agent scenarios the saving is enormous: up to 97% of the input there is repeating text, and without the discount you would pay full price for it at every step.
The practical technique: keep the unchanging part at the beginning of the request — that is what gets remembered — and the varying part at the end.
Part 2. What APIs cost now
Prices per million tokens as of 3 September 2026. Tariffs move fast, so this is a snapshot rather than a constant.
The cheap tier — for volume
| Model | Input ($/1M) | Output ($/1M) | Note |
|---|---|---|---|
| Qwen 3.7 Flash | $0.03 | $0.13 | the lowest widely available rate |
| DeepSeek V4-Flash | $0.14 | $0.28 | 98% discount on repeats |
| GPT-5.6 Luna | $0.20 | $1.20 | after the 80% cut from 30 July |
| Gemini 3.7 Flash | $0.75 | $3.75 | 50% introductory discount to year end, then $1.50 / $7.50 |
The middle tier — the workhorse
| Model | Input ($/1M) | Output ($/1M) | Note |
|---|---|---|---|
| Claude Sonnet 5 | $2 | $10 | the introductory price became permanent on 11 August |
| Gemini 3.1 Pro | $2 | $12 | |
| Qwen 3.8 Max | $2 | $6 | repeats — $0.25 |
| Grok 4.6 | $2 | $6 | by independent measurement |
| Kimi K3 | $3 | $15 | the cheapest in the flagship quality tier |
Flagships
| Model | Input ($/1M) | Output ($/1M) |
|---|---|---|
| Claude Opus 5 | $5 | $25 |
| GPT-5.6 Sol | $5 | $30 |
| Claude Fable 5 | $10 | $50 |
Sources: official provider price lists and the summary tables from CloudZero and BenchLM as of 3 September 2026.
Part 3. Why prices swing
Prices are not a constant: they fall under competition and rise under load, sometimes in the same week.
An example of a cut. On 30 July 2026 OpenAI cut the price of GPT-5.6 Luna by 80% — to $0.20 per million input — and simultaneously made GPT-5.6 Terra 20% cheaper. Two weeks later, on 14 August, Google shipped Gemini 3.7 Flash with a 50% introductory discount: $0.75 and $3.75 until year end, then $1.50 and $7.50.
An example of a rise. DeepSeek announced a new price list from 16 August 2026: the output of V4 Pro goes up noticeably, repeats become several times more expensive, and a double tariff is introduced during peak hours (official pricing).
And an example of a cancelled rise. Claude Sonnet 5 launched at an introductory $2 for input, and from 1 September that was due to rise to $3. On 11 August Anthropic announced the introductory price would become permanent and there would be no increase.
The last case is more useful than the first two: it shows that an announced tariff change is not yet a change. Planning a budget around an announcement that may not happen is as wrong as ignoring announcements altogether.
The planning conclusion: assume the price can change, and do not tie your economics to one provider without a fallback.
Peak and off-peak
Some providers introduce different tariffs for busy and quiet hours: more expensive by day, cheaper at night.
That is a way of managing load, not only of making money. If your tasks do not need an instant answer — overnight report generation, bulk processing — check whether such a tariff exists and when it applies in your time zone.
Part 4. Two payment models
Besides per-unit payment for text there is a second — for processing time. It is typical of image, video and audio generation.
For text models the count is almost always in tokens. For media it is often per second of generation or per finished result, because there are no tokens there in the usual sense.
The difference matters when planning. A token price is easy to predict from the length of the text. A per-second price is harder: it depends on resolution, duration and model.
Which is why for media it is particularly valuable when a platform shows the estimate before the launch rather than after.
Part 5. Costs that are not in the price list
The final bill often turns out larger than expected. Four reasons.
Hidden reasoning. With "thinking" models a stream of reasoning is added to the visible answer, charged at the output rate even though you never see it.
Tool calls. In agent scenarios every step drags the history of the previous ones with it, so a long chain costs disproportionately much.
Retries. Retries on external service failures multiply the spend if they are not counted.
Failed generations. The scene or the answer did not work, you regenerated — and you pay for every run, not only the successful one.
The practical conclusion: when planning a budget, allow not only for the ideal request but for reasoning, retries and redoing.
Which is exactly why transparent mechanics matter: so it is visible what the money was spent on, and so a failed generation is refunded to your balance rather than quietly charged.
Where these costs arise most often
The second of the four is the most expensive. Agent chains eat a budget fastest, because every step drags the history of the previous ones: the fifth step costs more than the first, the tenth more than the fifth.
And here is what matters: it is not that agents are expensive in themselves. It is that a badly assembled chain spins idle — takes unnecessary steps, asks again, repeats what is already done.
The difference between a careful and a wasteful chain on the same task is multiples, not percentages.
If you build agents and want them not to burn money: the express course “AI agents: the electrification of routine” — from your first automatic agent to chains running around the clock. Inside are 20 ready projects for real tasks and four working platforms: Make, n8n, Relevance, Lindy.
A ready project is valuable precisely because the chain in it is already laid out — you are not paying for your own experiments with redundant steps.
$9, included in the Make, N8N and Full plans. Not part of the three free Basic days: available as a one-off purchase or with a plan.
Part 6. How to calculate a project budget
The formula is simple:
number of requests × (average input + average output in tokens) × price per token
The order of work:
- Estimate how many requests a month your product makes
- Measure the average input and output size on several real examples
- Multiply by the price of the corresponding part from the provider's table
For agent scenarios add a multiplier for the number of steps and for the repeating text — this is where caching saves you, cutting the price of the unchanging part.
The figure you get is worth comparing against the cost of running an open model yourself: at large predictable volumes that often wins.
And build in a margin for price changes. As August 2026 showed, a tariff can fall or rise. A healthy budget is not a single figure at today's price list but a range with a fallback provider.
A worked example
The figures illustrate the method rather than any particular provider's tariff.
Suppose an assistant handles 10 000 requests a month. The average request is 1 500 input tokens (system instruction plus question and context) and 500 output.
At a notional $0.75 per million input and $3.75 per million output, one request costs:
1 500 × $0.75/1 000 000 + 500 × $3.75/1 000 000 ≈ $0.0011 + $0.0019 ≈ $0.003
Across 10 000 requests — around $30 a month.
Now switch on caching: if the system instruction (say 1 000 of the 1 500 input tokens) is unchanging and gets remembered, the input becomes several times cheaper and the monthly bill drops noticeably with no loss of quality.
What this calculation shows:
Output costs more than input. 500 output tokens cost more than 1 000 ordinary input ones. Asking for shorter answers is a direct saving.
Caching the unchanging part is the simplest lever. It requires no change of model and cuts the bulk of the input in stable scenarios.
For agent tasks, multiply by the number of steps. That is where spend grows fastest.
Part 7. How to keep costs down
Five techniques that work regardless of provider.
Cache the unchanging part. Keep the system instruction and the permanent context at the start of the request.
Ask for shorter answers. Output costs more than input; with "reasoning" models, limit the volume of reasoning where it is not needed.
Set a cheap model as the default. Route only the difficult steps to the expensive one — by teams' experience this delivers the bulk of the saving.
Count cost per success, not per token. In agent chains what matters is the price per solved task; strip out unnecessary steps. More detail in the AI agents hub.
Consider running your own. At large volumes an open model on your own hardware often works out cheaper and is not exposed to anyone else's price rises — the comparison is in the Best open LLMs 2026 hub.
Deferred processing
If the answer is not needed this second, the cost can be reduced appreciably.
Off-peak — a reduced tariff during quiet hours. Bulk processing and report generation sit there conveniently.
Batch mode — asynchronous processing of a large volume at once, often charged at less than an ordinary call because it loads the provider's hardware better.
The practical conclusion: split tasks into urgent (ordinary call) and deferred (batch and off-peak). That alone cuts the bill without changing anything about quality.
Part 8. Three payment strategies
A simple division helps pull it all together.
Ordinary API per call. Worthwhile at small and irregular volumes, where keeping your own hardware makes no sense and speed of launch matters.
API in batch and off-peak mode. The same provider but deferred processing at a reduced price. Worthwhile for large regular volumes where the answer is not needed immediately.
Running an open model yourself. Worthwhile at large predictable volumes, where the saving outweighs the cost of hardware and which also gives independence from other people's price rises.
Most mature products combine all three: urgent work through the ordinary API, bulk and deferred work in batches, the largest and most stable load on their own hardware.
The starting point for the choice is the profile of your load — volume, urgency, data sensitivity — rather than "the cheapest price on paper".
Part 9. Open alternatives
Moving to open models reduces exposure to API pricing: they can be run on your own hardware, and then the price stops depending on anyone else's tariffs.
The current generation is competitive on quality: DeepSeek V4 under MIT, Qwen 3.8, GLM-5.2, Muse Glimmer 30B under Apache 2.0. Weights under free licences can be used commercially — a detailed comparison and the hardware requirements are in the Best open LLMs 2026 hub.
An important nuance: open weights does not mean free. You do not pay for tokens, but you do pay for hardware and maintenance, so the gain appears at large volumes.
Another route to lower costs is the open tooling around models, gathered in the Open Source section: it removes part of the infrastructure spend.
Your own operator instead of a browser tab
A separate case worth knowing if token costs genuinely concern you.
Ordinary assistants live in a tab: close it and they forget you, and every call is metered. There is another approach — a background service on your own hardware: it runs continuously, remembers you between sessions and does not bill per request.
Plus two properties a tab cannot have at all: it initiates contact itself when an event fires, and it connects where you already are — in messengers.
The express course “OpenClaw: not a browser assistant but your own AI operator” covers deploying such a service. What you end up with: a working operator on your hardware connected to WhatsApp, Telegram, Discord, iMessage and Slack, a library of 50+ skills and a configured memory system.
Who genuinely needs this: anyone with a large stream of similar requests, anyone with data that cannot leave the building, and anyone tired of paying per call.
Who does not: if the tasks are one-off and the volume small, ordinary tools cover the same ground more cheaply and without configuring hardware.
$9, included in the Make, N8N and Full plans. Not part of the three free Basic days.
Part 10. How this concerns you if you take on jobs
The section usually missing from pricing overviews. And for a freelancer it matters more than the rest of the article.
The main mistake: counting the month instead of the job
The spend is smeared out: the subscription went out a month ago, generations run in the background, and profit is counted as "what landed in the account".
That is how people work at a loss for months without noticing.
The right question is: what did this job cost me.
The job brought in $40 and cost $3 to run — seven percent, fine. It cost $20 — the problem is not model pricing but the process.
Build the spend into the quote
The cost of generations goes into the client's price the same way paper goes into a printer's.
No client asks a printer what the paper cost. He pays for the print run.
A way to estimate: work out the spend for the task, multiply by two — for misses and revisions — and build that in. If it comes to more than five to seven percent of the fee, either the job is too cheap or the process is too wasteful.
What not to do: put the spend as a separate line on the invoice. The client will start discussing the cost of generations rather than the result, and you end up in a conversation with nothing to win.
What to compare against: what the work pays
From a scrape of 5 986 jobs over four months: the median one-off job is around $60. A short clip $18–45. A logo $25–90. A multi-page site $245–730. A system or a pipeline $490–1 460.
A caveat: an explicit budget appears in 17% of listings, and by individual type of work there are between twenty and three hundred observations with a figure.
What this means for the arithmetic. With per-use payment the cost of an operation is measured in cents and single dollars. Which means the very first completed job covers the cost of several dozen attempts.
The whole problem is one of order. A subscription demands money before the first job. Paying for usage lets you start with a sum you do not mind losing and pay out of what you earn from then on.
Three things that break the economics
Generating on the off-chance. Twenty attempts instead of four because the task was not defined. A precise description is a direct saving.
An expensive model on drafts. The spread on video runs from $0.22 to $11.95 per generation — fifty times. Run drafts on the cheap one and the final on the one you need.
Revisions without a boundary. For generative video a revision often means regeneration, which means a new cost. Two rounds in the quote is normal; "we revise until you like it" is an open tab at your expense.
Part 11. How this works here
On the platform the price of a request is not blind credits but actual token spend.
The prompt generator and the chat layer count it on the facts: input, output, cache reads and writes. What is charged is what you actually spent, not an abstract tariff.
What that gives in practice:
The estimate is visible before you press. You see the cost of an operation before launch, not after.
On a failure before the answer, the money is returned to your balance.
Repeat requests get cheaper thanks to remembered context.
This follows directly from the token economics the whole guide is about: the spend is counted in the same units in which it arises, and the user sees exactly that.
A wallet instead of a subscription
Worth a separate note, because it removes the main objection.
From my audience survey, word for word: "the cost of these models is high, the subscriptions are very expensive, there is no room to experiment".
The person is right. To try three models for different tasks you need three subscriptions, each charged in full whether or not you worked that month.
A wallet works differently: you are charged for what is done. Did not open it for a week — spent nothing. A month without work costs zero. The entry threshold is low: you can start with a sum you do not mind.
Room to experiment appears exactly when an experiment stops costing as much as a monthly subscription.
Part 12. What to open for your own task
A wallet with pay-as-you-go — available at any level, including free registration.
Ready assistants — over 200 across 14 categories. Often there is no need to look for a tool at all: a ready assistant for the task closes it without comparing services. Basic plan.
An encyclopaedia of 198 vetted services — a reference to search by task rather than read through. Included in Basic.
Prompt engineering — a foundation course with a map of the model landscape: which one is for what. It helps you avoid paying for a subscription to a tool you do not need. $9, included in Basic.
Cerebrum — if the task repeats or has several steps: describe it in plain words in the chat, the right models are picked automatically, the price is visible before launch, and charging is from your balance based on actual use.
The “AI agents” express course — if you build chains and want them not to spin idle. 20 ready projects, four platforms. $9, the Creator, Make, N8N and Full plans.
The “OpenClaw” express course — if you want to stop paying per request: your own background operator on your own hardware with local memory and messenger connections, 50+ skills. $9, the Make, N8N and Full plans.
Neither is part of the three free Basic days — a one-off purchase or the corresponding plan.
Price chronicle
Prices move almost every week: some cut under competition, some raise under load, others introduce launch discounts.
During August 2026 Google halved the price of Gemini 3.7 Flash at launch, while DeepSeek raised the V4 Pro tariffs from 16 August.
Changes are tracked in the daily AI digests. For how agents work and what a turn costs, see the AI agents hub; for the "run your own instead of an API" option, the Best open LLMs 2026 hub.
FAQ
Why does the answer cost more than the request?
Because generation takes more computation than reading. The model processes your request whole and at once, while each word of the answer is computed sequentially.
Hence the difference in price, often 2–5 times. The practical conclusion: a long answer costs more than a long request, so ask for shorter answers where you can.
With "reasoning" models, billed hidden reasoning is added to the output.
What are cached tokens and why are they cheaper?
They are the part of the input the provider has already processed and keeps: an unchanging system instruction, or a document you send with every request.
There is no need to recompute it, so it costs several times less than ordinary input — with some models the discount reaches 98%. In agent conversations, where up to 97% of the input is repeating text, caching saves the bulk of the bill.
Keep the unchanging part at the beginning so that it gets remembered.
Which is cheaper — an API or running your own?
It depends on volume.
For small and intermittent loads an API is usually better value: no hardware to keep. For large and predictable volumes running your own often works out cheaper, and the price becomes predictable and immune to other people's rises.
Plus independence: open weights cannot be revoked. A comparison of models and hardware requirements is in the Best open LLMs 2026 hub.
How fast do prices change?
Fast — sometimes several times a month. Providers cut under competition, raise under load, introduce discounts and peak tariffs.
So verify any specific figure, including the ones given here as of 3 September 2026, on the official pricing page before deployment. And do not tie your product's economics to one provider without a fallback.
What are off-peak and batch mode, in plain words?
Two ways to pay less when the answer is not needed this second.
Off-peak — a reduced tariff during quiet hours: the load is easier for the provider to serve, so the same tokens cost less.
Batch mode — processing a large volume at once, charged at less because it loads the hardware better.
Split tasks into urgent and deferred — that alone cuts the bill with no loss of quality.
How much should I allow for generations if I take on jobs?
The rule: the spend goes into the client's price the same way paper goes into a printer's.
Estimate the spend for the task, multiply by two for misses and revisions, and build it into the quote. If it comes to more than five to seven percent of the fee, either the job is too cheap or the process is wasteful.
For reference: the median one-off job on the market is around $60, while the cost of an operation on pay-as-you-go is measured in cents and single dollars. The very first completed job covers the cost of several dozen attempts.
Do not put the spend as a separate line on the invoice — the client will start discussing the cost of generations instead of the result.
Try it
Registration is free and opens three days of full Basic access — all 200+ assistants, the encyclopaedia of 198 services, the prompt texts, the skill files, the ten-lesson sales module and six Basic mini-courses.
Three days is a way to test not the tools but yourself: work a chain through to the end and look at your own result, having paid nothing.
One action right now. Open the list of your subscriptions and count how many times you opened each of them in the past month.
Usually it turns out the money goes on two or three while the work happens in one. That is your saving — with no choice of plan involved.
What to take on the platform for this task
- Circuit breaker for n8n agents against hangs and overspending — a spend cap, an iteration limit and a kill switch for agents; n8n template, Creator, Make, N8N, Full
- Jan — an offline AI chat on your own computer — run open models locally, no subscriptions; Open Source (description open to all, repository link from Creator)
- DeepSeek — open LLMs for reasoning and code — open weights for self-hosting; Open Source (repository link from Creator)
- Strategic Consultant — launching a freelance business on AI skills; assistant, from Basic
- Cerebrum — a task in plain words, the price visible before launch, payment from the balance by actual use
What to read next
What it costs to try — a wallet instead of a subscription, and prices by mode.
Which plan to choose — the exact contents of each of the six.
It was expensive — now it is $9 — what is open for free right now.
What is on the platform — fourteen sections in three parts.
What a clip costs you — the other half of the equation for a contractor.
Local models for sensitive data — when your own hardware is cheaper.
The market in full: 5 986 jobs — what to compare your costs against.
The AI freelancer price list — what to charge for the work.
What you will be able to do in a month — what this is being paid for.
Build once, runs always — the chain estimate is visible before launch.
n8n and Make automation templates — where spend grows fastest.
Skills for Claude Code — how chains work and what they cost.