DeepSeek V4.1 Flash Finds CVEs at $2.40 — AI Digest
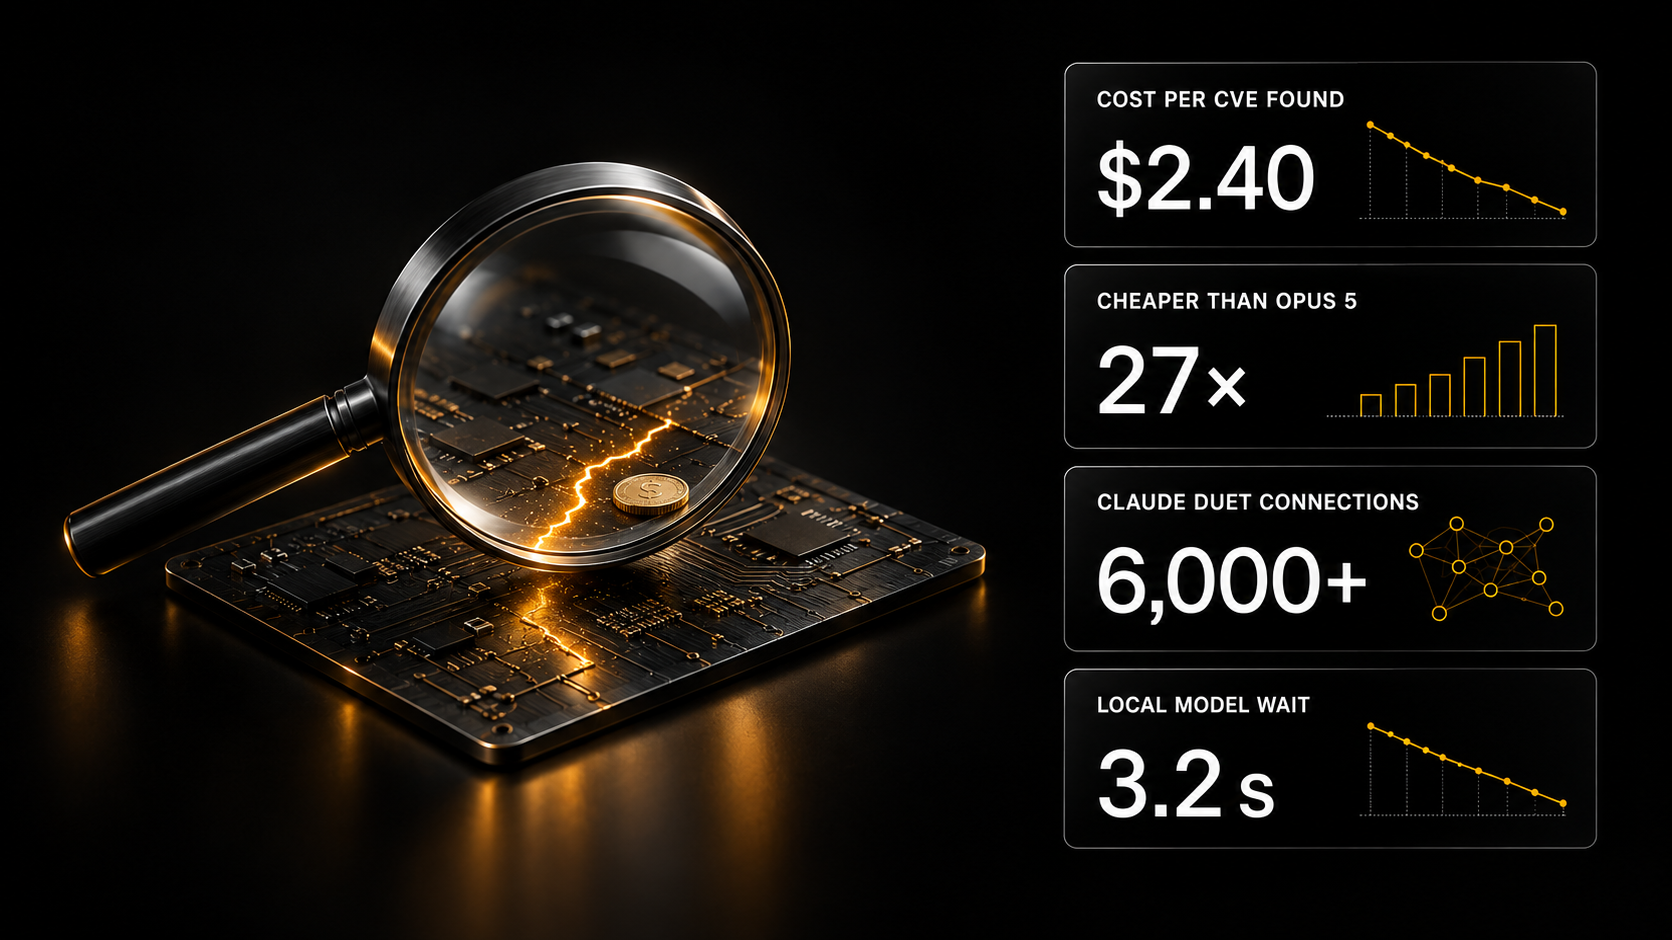
DeepSeek V4.1 Flash finds 87.5% of known test vulnerabilities at $2.40 per finding — 27 times cheaper than Opus 5. Also: inside Claude Duet, a local model without the long wait, and why 5 of 9 models failed to profit on the market.
Today's main point for you: checking code for known vulnerabilities now costs $2.40 per finding — that is what DeepSeek V4.1 Flash spent in an independent test, against $64.96 for Opus 5. If you ship websites or bots to clients, you can afford to run such checks regularly. Keep the boundary in mind, though: finding a known hole and finding a new one are different tasks, and models are still weak at the second.
Today's top stories
DeepSeek V4.1 Flash: a known vulnerability for $2.40 — 27 times cheaper than Opus 5
DeepSeek V4.1 Flash found 87.5% of the known vulnerabilities in a test set and spent $2.40 on each finding, according to a measurement published on October 22, 2026.
Only GPT-6 Astra scored higher, at 90.6%, but each of its findings costs $135.23. With Opus 5, one found vulnerability costs $64.96. I did the math: DeepSeek V4.1 Flash is 27 times cheaper than Opus 5 and 56 times cheaper than GPT-6 Astra, with a 3.1-point gap in the share of findings.
A CVE is a public ID for an already known vulnerability in a shared registry. The result was scored as pass@3: the model got three attempts, and one success was enough.
What it means: your wallet. Running your own or a client's code against known vulnerabilities now costs a few dollars rather than dozens. This is a search for known issues, not a security audit — describe the service that way in the contract.
Sources: measurement
Claude Duet: 6,000 connections and a confirmation before every payment
Claude Duet is Anthropic's proactive agent built on Opus 5.5: it watches connected services on its own, assembles a priority brief and runs background tasks in its own virtual machine and browser.
Claude Duet has more than 6,000 connections, including Gmail, Slack, QuickBooks, Stripe, Shopify, Docusign and HubSpot. The agent sends messages, makes payments, signs documents and deletes things only after a person confirms; credentials are isolated from the model. Access is for now through a waitlist for Pro and Max subscribers in the U.S. On October 25, 2026, the host of The AI Daily Brief compared Claude Duet with ChatGPT Dots and explained why proactive agents may finally be finding a place in his work.
Two safeguards appeared alongside: 1Password for Agents fills in a password without showing it to the agent, and Composio Firewall checks every agent action and every service response.
What it means: business. A shop or a salon gets an agent that handles email, payments and the storefront, while a person confirms each payment. I would start with read-only access and add one service at a time.
Sources: Anthropic · r/singularity · The AI Daily Brief · 1Password for Agents · Composio Firewall
MAFDET: a local model thinks while you type — the wait drops from 12.2 to 3.2 seconds
MAFDET is an open-source front end for local models built on llama.cpp that starts computing before you press Enter and cuts the wait for an answer almost fourfold.
On an RTX 2060 graphics card with 6 GB of memory, the average wait after Enter for Qwen3-4B fell from 12.2 to 3.2 seconds, with all 24 word problems solved correctly. For Qwen3-14B, which only half fits in memory, it fell from 108 to 47 seconds. The program sets itself up for CUDA or the CPU automatically.
A KV cache is the model's memory of the text it has already read: fill it in advance and there is nothing to recompute after Enter. MAFDET fills it as you type and, for Qwen3, also drafts its reasoning ahead of time. Commenters warn that if you change a number in a question you have already typed, the model may answer the draft.
What it means: client work. A department assistant whose documents must not leave the building usually draws one complaint — "it thinks too long." Now the wait is noticeably shorter even on an old graphics card.
Sources: r/LocalLLM · repository · open-source LLM guide
Quant-Arena: only 4 of 9 models made money on a sealed year of trading
Quant-Arena, launched on October 22, 2026, let 9 models trade on a full year of Chinese stock data hidden from them in advance — only 4 finished in profit.
A-shares are shares of mainland Chinese companies traded in yuan. A sealed year means the model could not have seen the outcome in its training data.
The same day, Latent Space released a conversation with Anekha Sokhal, a former energy-derivatives trader. Her company, Moshi, is building a recommendation engine that connects the flood of market information to a specific trader's positions; she describes the product as a mix of Bloomberg, Claude and Netflix.
What it means: profession and trust. For a financial professional, AI is already useful for sorting news against a portfolio. Handing it the trading decision is premature: on an honest test, more than half of the models did not make money.
Sources: Quant-Arena · Latent Space
Agent Relay and Handoff: one working context for Claude Code, Codex and Cursor
Agent Relay is an open-source tool, released on October 23, 2026, that lets agents read each other's sessions, ask questions and hand off work across Codex, Claude and Conductor.
There is no new model in Agent Relay: it solves coordination between agents running in different programs. A neighboring open-source project, Handoff, does the same through a file: the state of the work is saved once, and any agent picks it up — Claude Code, Codex, Cursor, Copilot or Gemini CLI.
A harness is the scaffolding around a model: tools, memory, rules. If the model is the chef, the harness is the kitchen, and both projects fix the kitchen, not the chef.
What it means: for the technically minded. A project you run in two agents no longer has to be re-explained from scratch to every new session: the context moves together with the work.
Sources: Agent Relay · Handoff
Agent4Sci: three skills doubled Opus's gain — from 10.4% to 20.1%
In Anthropic's Agent4Sci study, agents beat the best published result on all 20 scientific ML benchmarks, and three scaffolding skills raised Opus's average gain from 10.4% to 20.1%.
A skill is a file of instructions and techniques that an agent loads for a specific task. A separate study, World of SWECraft, spent more than 10,000 agent-hours on interdependent software packages and reported up to a 1.31-fold efficiency gain. The authors noticed that some frontier models stop looking for improvements even when opportunities remain: persistence is a separate quality, not the same as model strength.
What it means: for the technically minded. Before paying for a more expensive model, give your current one better skills: in Agent4Sci that doubled the gain without changing the model.
Sources: Agent4Sci · World of SWECraft · Claude Code skills guide
DeepSeek and MiniMax cleared China's export registration: open weights will keep coming
DeepSeek and MiniMax completed registration with China's Ministry of Commerce required by new temporary AI export-control rules, the Chinese outlet Yuyuan Tantian reported on October 22, 2026.
According to the outlet, the registration lets both companies keep publishing open weights abroad, sign international partnerships and ship model updates. We covered China's draft export-control amendments in the October 17 issue. Discussion participants expect Zhipu and Alibaba to go through the same procedure.
Open weights are the files of a trained model that you can download and run yourself; training code and data usually do not come with them.
What it means: for the technically minded. Anyone building on DeepSeek V4.1 Flash or MiniMax M3.1 Flash locally now faces less risk that the next version will not be published.
Sources: r/LocalLLaMA · Yuyuan Tantian · Open Source on AI SKILLS
Numbers and facts
Our own summary: what one found known vulnerability costs with different models, per the measurement of October 22, 2026.
| Model | Share found (pass@3) | Price per finding | How many times pricier than DeepSeek V4.1 Flash |
|---|---|---|---|
| DeepSeek V4.1 Flash | 87.5% | $2.40 | — |
| Opus 5 | no data | $64.96 | 27× |
| GPT-6 Astra | 90.6% | $135.23 | 56× |
Source of the figures — measurement; I calculated the ratio column.
- $0.04 per million input tokens is the price of SubQ Snap 1.1 with a 384,000-token context; on the Artificial Analysis Decision Index it scored 65, level with d1-ultra and Elephant 9B (Artificial Analysis).
- $0.21 per 1,000 claims is what d1-ultra costs on ClaimBench, where it handled every claim correctly (Vals).
- 0.5 billion parameters in Ant's Ming-3.0-tts — an MIT-licensed speech model that made the top tier of the Artificial Analysis ranking (Artificial Analysis).
- 41.5% versus 36.2% — an 8-billion-parameter Qwen3, trained by Meta, picks the right tool from a catalog of 10,000+ entries on ToolBench G3 after reinforcement learning, versus supervised fine-tuning alone (summary).
- 325 TFLOPS in BF16 at 600 W for the Huawei Ascend 950PR accelerator — about 44% of an H100 (measurement).
- 12% faster generation for DeepSeek V4.1 Flash on four RTX 6000 Pro cards after swapping in new kernels for data exchange between the cards (kernels).
Different views: can defense keep up with AI that finds holes?
DeepSeek V4.1 Flash finds 87.5% of the known vulnerabilities in a test set at $2.40 per finding, but models are much worse at new bugs: according to SWE-sweep, even GPT-6 Astra finds fewer than 10% of real bugs.
- For. Joshua Saxe argues that growing capability does not immediately bring an equal growth in damage: adoption inside organizations, talent, access to models and law enforcement hold attackers back, so defenders have a temporary window — which does not mean the capability is harmless (Joshua Saxe).
- Neutral. By SWE-sweep's count, OpenAI and Anthropic models now find twice as many bugs at half the former cost, but the share of real bugs found is still under 10% (SWE-sweep).
- Against. A video spread on Reddit in which Sam Altman, according to the poster, says: "I no longer think we're gonna be able to patch all the bugs"; the video itself could not be verified. And METR and Redwood Research auditors, who reviewed agent oversight inside OpenAI, found that after context compression about 10% of eligible internal Codex traffic went unmonitored (r/OpenAI, summary).
Tools and techniques
- Track vulnerabilities without technical bulletins. cve.now pulls together four CVE feeds and explains every entry in plain English (cve.now). What you get: a minute to see whether a new hole affects the website or bot you delivered to a client.
- Let the agent fix, not just find. Cognition open-sourced a plugin that lets an agent remediate vulnerabilities (Cognition). What you get: after a code check, a ready fix for review instead of a list of problems.
- Host a prompt library for your team. prompts.chat is an open collection of prompts with 174,500 stars on GitHub that you can deploy on your own server for the whole organization (prompts.chat). What you get: a shared prompt base without sending data outside; ready-made templates are also in the AI SKILLS prompt library.
In brief
- Claude limits: SemiAnalysis claims Anthropic is testing new limits on some users — about 20% less monthly value at API prices, but higher five-hour limits (SemiAnalysis).
- ClinePass: Kimi K3.1 Pro is available in Cline through a $9.99-a-month plan with discounted access to open models (Cline).
- Datadog: the company reportedly offered nearly $4 billion for Upwind Security, according to The Information (The Information).
- OpenAI: according to the WSJ, the three researchers fired in September 2026 had pushed to keep models' chain of thought visible (Maxwell Zeff).
- Jon Barron: found 2 numerical issues in the standard softmax and cross-entropy implementation; Gemini Flash spotted the first one (research).
- Math: Latent Space explains why models have become strong at math — starting with an internal OpenAI model's counterexample to Erdős's unit distance conjecture, open since 1946 (Latent Space).